Pinecone's Nexus cuts agent tokens 150,000 to under 1,000
Edo Liberty argues enterprises are repeating the "am I fat?" mistake from Yahoo Answers with AI agents today — asking systems to know things they structurally cannot. His fix is not a smarter model but a separate, persistent knowledge layer that treats every agent as a brilliant new hire who starts each session knowing nothing about the company.
- Yahoo Answers origin — Liberty traces the idea to Yahoo Answers roughly 15-16 years ago, where users asked a Q&A forum 'am I fat?' — a question the product had no way to answer, illustrating a broken theory of mind between users and AI.
- Three kinds of knowledge — He splits knowledge into general knowledge (public, absorbed in training), specific knowledge (contracts, codebases, already solved by RAG and vector search, including Pinecone's own vector DB), and tribal knowledge (company processes, ownership, culture) which cannot be pulled from any single document.
- Agent as new hire — Liberty says the right mental model for enterprise agents is a brilliant, well-tooled new hire who is clueless about the company, has to read documents from scratch, and starts every session like day one on the job.
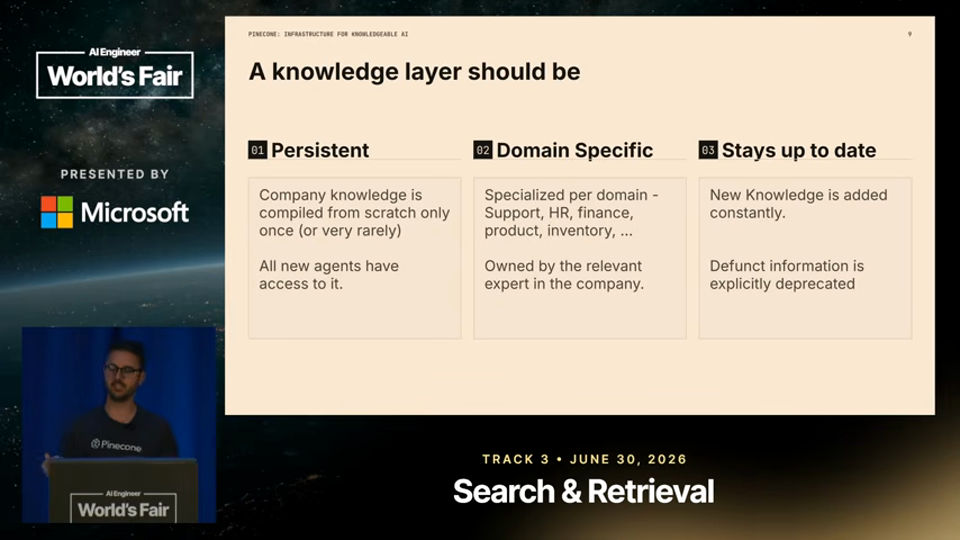
- Knowledge layer requirements — He defines a knowledge layer as needing to be persistent (built once, rarely rebuilt), highly specialized by domain and owned by domain experts, and constantly kept current.
- CEO example — He illustrates the currency problem: if a company replaces its CEO, everyone knows by the next day even though 9,000 documents spanning the last 10 years still name the old one, and that new fact must override all of them.
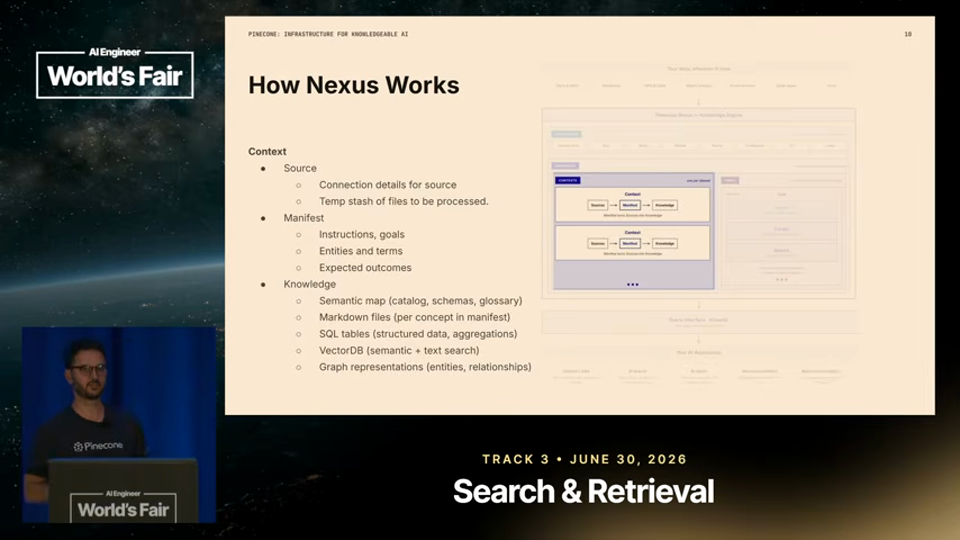
- Nexus product overview — Liberty introduces Nexus, Pinecone's knowledge layer product, structured around four parts: connectors, context, tasks, and queries (NoQL).
- Context and manifest — Context is organized per topic (HR, operations, engineering) via a manifest — a novel component where users specify what tasks and entities matter, replacing hand-written skills, plugins, and markdown commands.
- Five content types — Each context stores a semantic map, unstructured markdown files (an idea he compares to Andrej Karpathy's 'LLM wiki'), SQL tables, a vector database, and knowledge graphs, all managed automatically.
- Task verbs — The system supports import (ingest new data), curate (the most elaborate function, updating tables, graphs, and indexes using the manifest and semantic map), and search (an internal abstraction layer).
- NoQL queries — NoQL lets an agent specify a token or dollar budget for how much effort to spend answering, returning agent-formatted grounded text rather than a chat response.
- Runtime coding agent — Nexus answers queries by writing and executing code live, like a Jupyter notebook or Python REPL, iterating until it gets the right answer, rather than deploying a fixed piece of software.
- Token reduction — Liberty says this approach cut prompting from about 150,000 tokens down to under 1,000 tokens needed to specify interfaces for getting information out of Nexus.
- Early results and launch — Early access customers saw 77-90% token consumption reduction, 20-77% faster performance, and higher accuracy across domains; Nexus moves from early access to public preview the day after the talk.
In their words
They have no idea about your company's goals, culture, priorities, processes.3:59
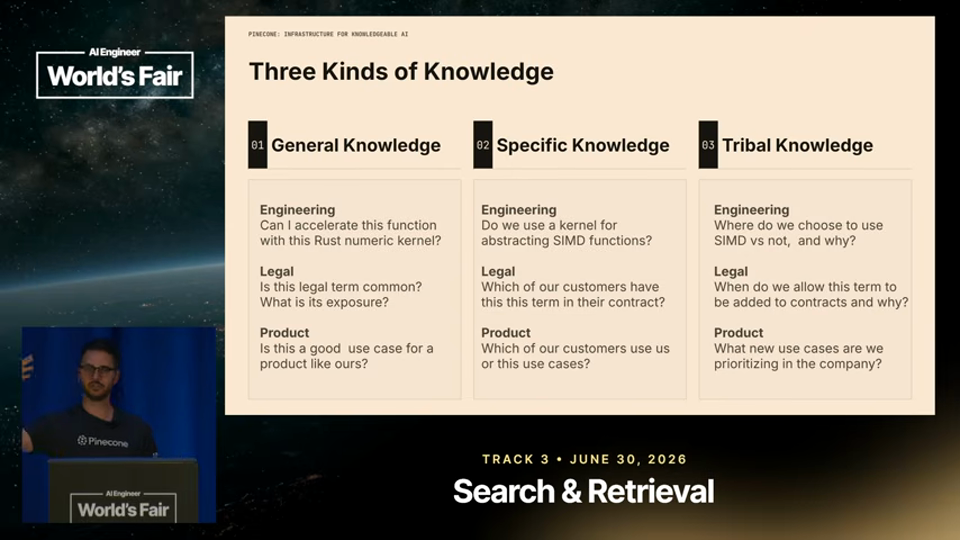
If the company replaces its CEO, the very next day, everybody in the company knows who the CEO is. Okay? Even though 9,000 documents going from, you know, a day before yesterday to uh the last 10 years say it's somebody else.6:15
In a knowledge layer, you don't do that anymore. Okay? You tell the you tell the knowledge layer, you tell Nexus what you care about in a manifest.9:07
We went down from having something like 150,000 tokens to give our agents all the tooling they need to less than a thousand tokens to specify all the interfaces they need to get information out of Nexus.16:48
Disclosure · Edo Liberty is the founder of Pinecone and is presenting Pinecone's own product, Nexus.
One thing to add — One thing to add — the token and speed figures (150,000 to under 1,000, 77-90% reduction) come entirely from Pinecone's own early-access customers and were not independently verified in the talk. It's worth watching whether "runtime coding agent" architectures hold up outside curated enterprise demos before treating the comparison as a fair fight.
One thing to try tonight
Try writing a "manifest" file for one internal domain (e.g., your team's on-call process) listing what tasks and entities matter, then see whether an agent given only that manifest performs better than one given your usual scattered markdown/skills files.